Senior Data Scientist · Production ML

From messy data
to real-world
decisions.

I’m Sergey Orlov. I build and own ML systems that turn financial, behavioral, and document data into reliable decisions—from the first model to the production service.

Credit risk & decisioning / Applied AI / ML engineering

MLmodel development & evaluation
Datapipelines & analytical foundations
Shipdeployment & monitoring
Owndesign through ongoing operation
01 / Production work

Models are only part
of the system.

My strongest work connects modeling, software engineering, and operational decisions. I take responsibility for how the complete system behaves.

Document intelligence

Make extraction earn its way into a decision.

Document-processing and data-quality workflows that turn unstructured inputs into usable analytical data.

How I approach reliability
Data engineering & analytics

Own the path from legacy data to trusted BI.

Analytics platform development spanning ingestion, data modeling, reporting, and maintenance. Public examples illustrate general engineering patterns.

Read the data engineering case
02 / Code you can inspect

Engineering judgment,
made visible.

Four focused labs demonstrate how I structure, evaluate, and reason about ML systems. Each includes source code, tests, and a reproducible local workflow.

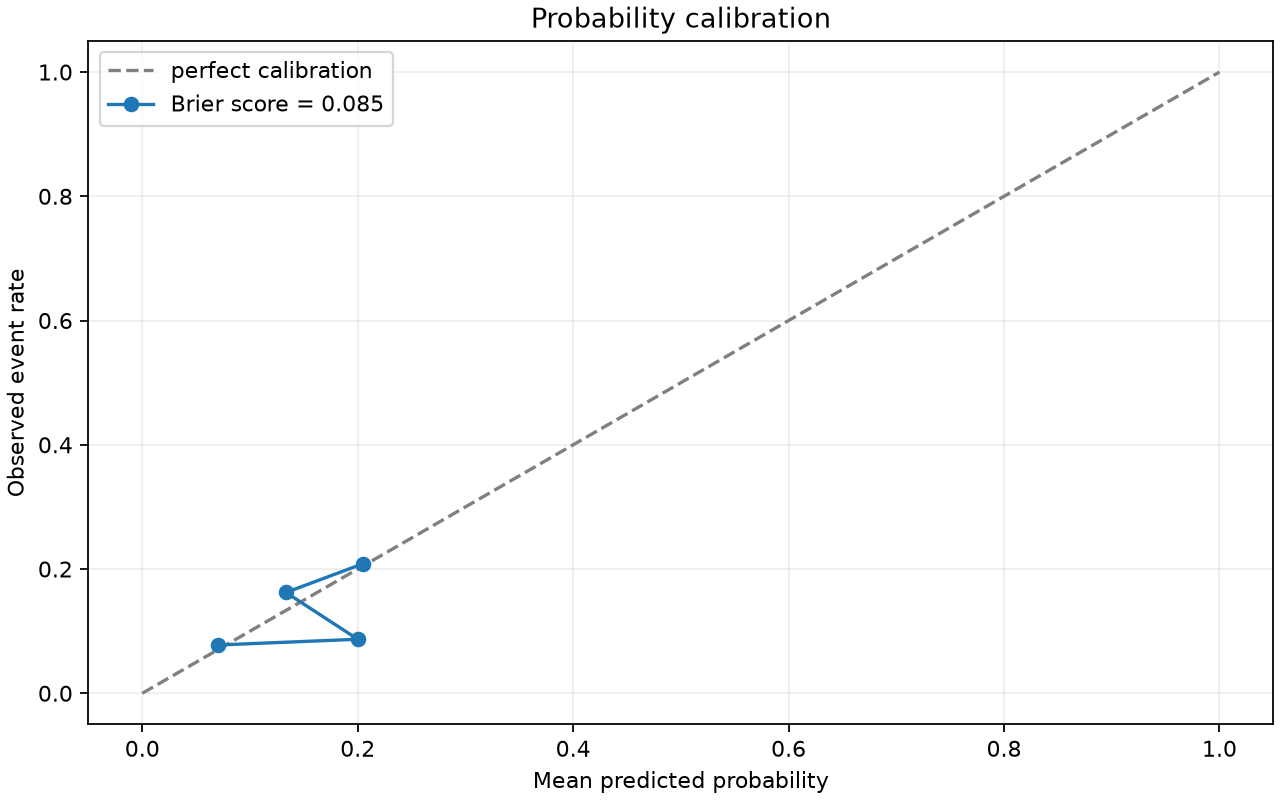
Calibration chart from the synthetic Open Decisioning Lab evaluation
01 / Public reference project Synthetic data

Open Decisioning Lab

Model scores. Explicit policy. Traceable decisions.
A calibrated synthetic classifier with a separate policy layer, stable reason codes, typed API contracts, and a reproducible holdout evaluation.

Calibration Policy separation FastAPI
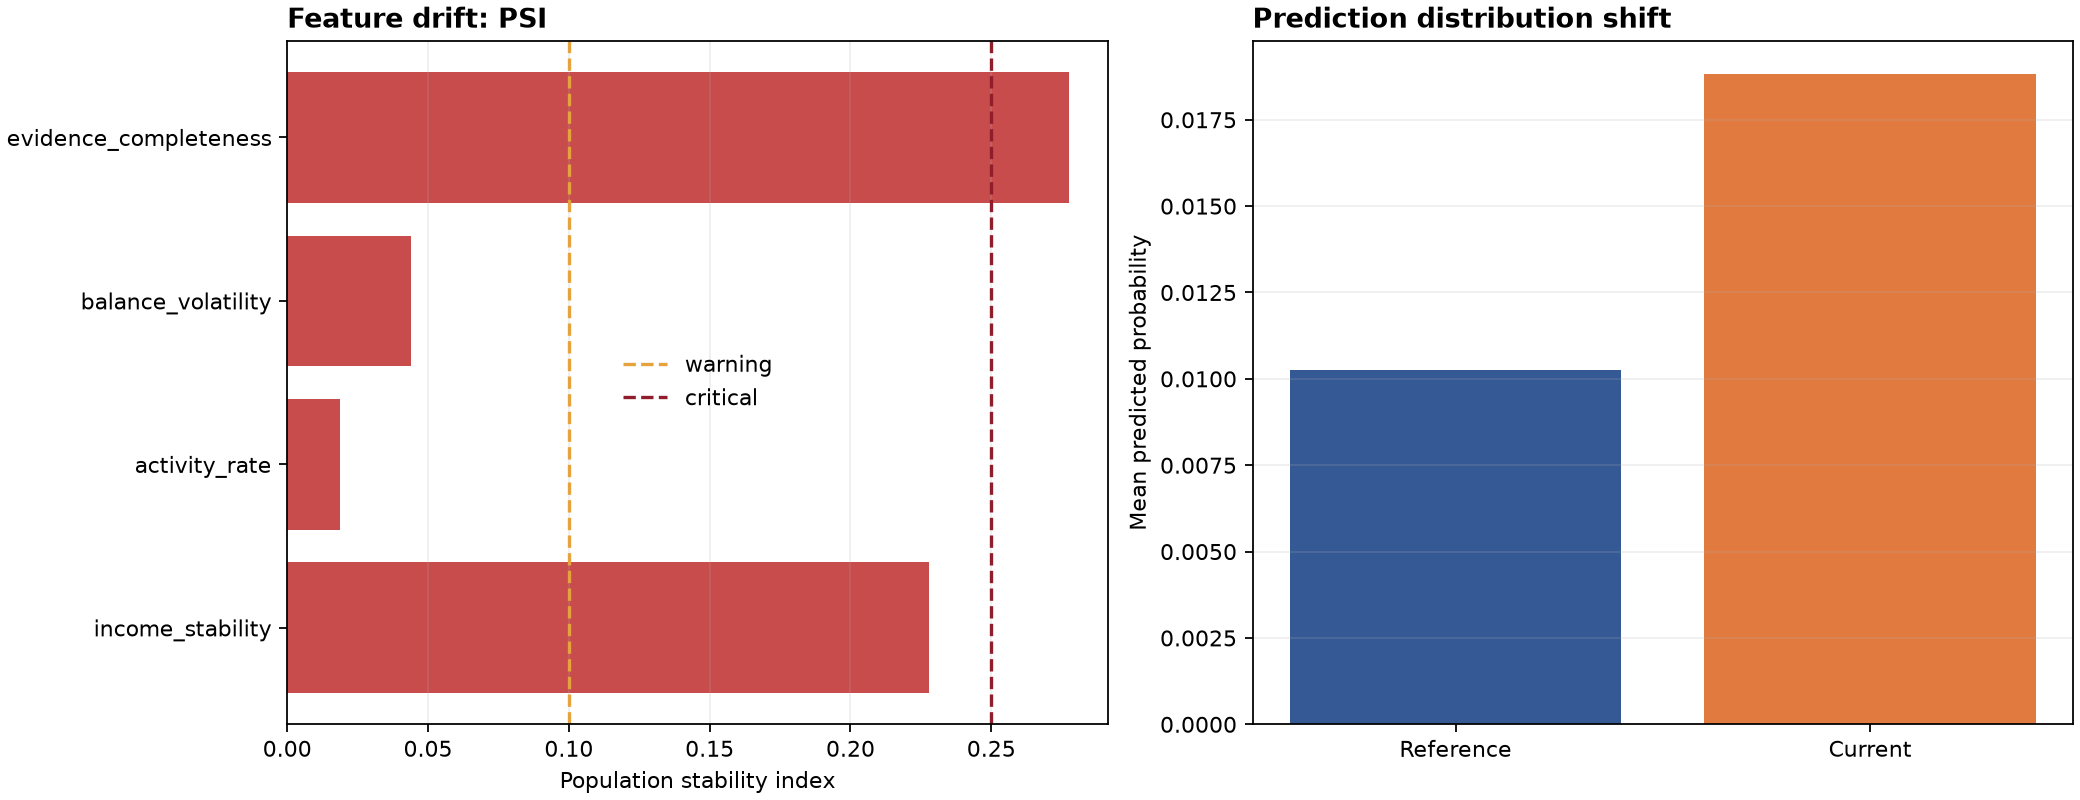
Synthetic model monitoring dashboard with drift and calibration diagnostics
02 / Public reference project Synthetic data

Default Risk Lifecycle Lab

What happens after a model ships?
Chronological evaluation, label maturity, as-of history features, drift diagnostics, and explicit recommendations to keep, investigate, recalibrate, or roll back.

Model monitoring Label governance Shadow models
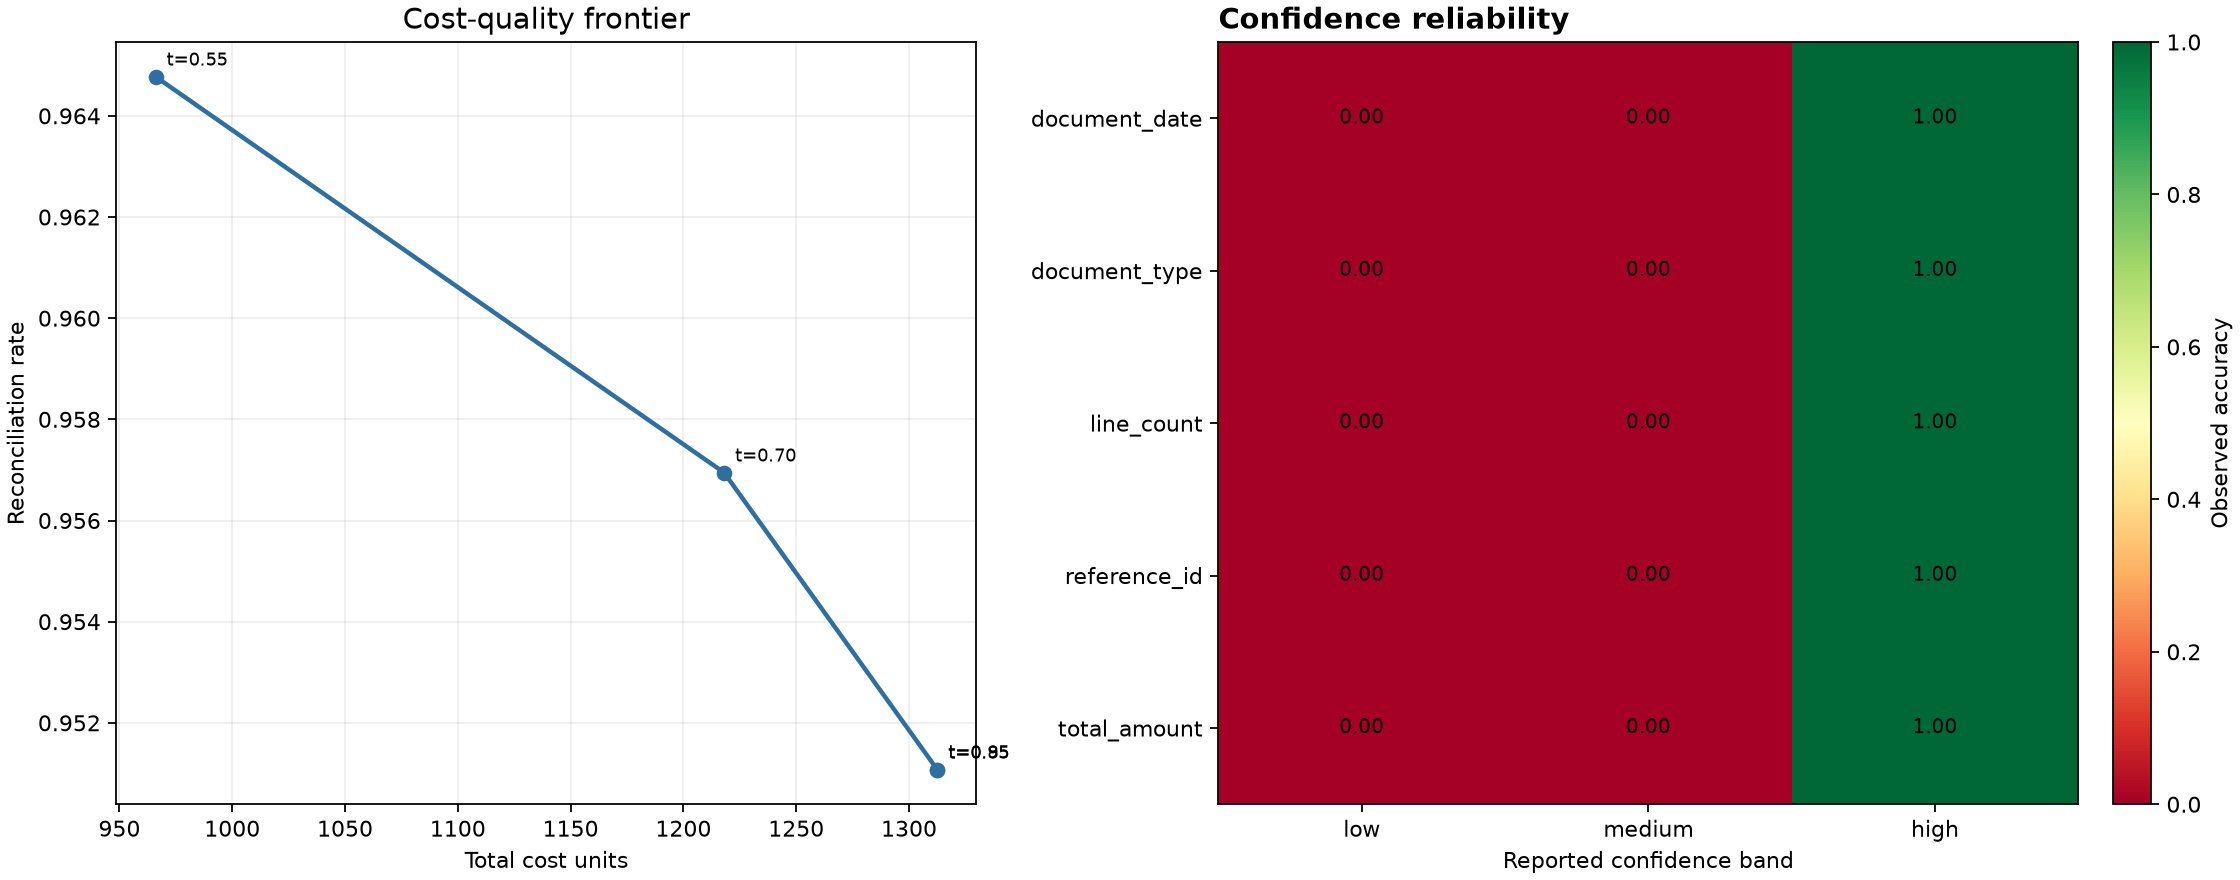
Cost and quality frontier from a synthetic document extraction benchmark
03 / Public reference project Synthetic data

Document AI Reliability Lab

Measure extraction quality before trusting it.
Controlled corruption, field-level metrics, reconciliation, and accept/review/reject gates. A synthetic extractor cascade explores the trade-off between quality, latency, and cost.

Quality gates Failure analysis Evaluation
Synthetic transaction workflow
01 normalize descriptions & amounts
02 flag duplicate transactions
03 classify positive-credit income
04 measure cadence & variability
05 build per-entity features
04 / Public reference project Synthetic data

Cashflow Intelligence Lab

Turn irregular transactions into usable signals.
A compact synthetic prototype for transaction normalization, duplicate detection, rule-based income classification, cadence analysis, and cash-flow feature engineering.

Feature engineering Pandas Income cadence

These are independent demonstrations using synthetic data—not copies of employer systems or evidence of production performance. Document AI’s cloud adapters are optional integration boundaries; its default benchmark uses simulated extraction. Charts shown here are committed outputs from the linked repositories.

Earlier geospatial research
03 / The longer view

A quantitative foundation.
A builder’s mindset.

My path runs from computational physics and high-performance computing to applied machine learning and financial decision systems. The common thread: make complex systems measurable, explainable, and useful.

I’ve led research and engineering teams, mentored emerging practitioners, and stayed close to the implementation. Today, my focus is hands-on ownership of models and the systems around them.

PhD, Physical & Mathematical Science
Tomsk State University · 2012
Master of Data Science & Analytics
University of Calgary · 2023

Outside work, you’ll usually find me hiking, cycling, or spending time in the Rockies.

2024–present

Cashco Financial

Data Scientist

Own credit decisioning, risk models, bank-data intelligence, and the analytics platform—from design to production operations.

2023–2024

Cybera

Data Scientist

Entity resolution with transformer embeddings and retrieval; distributed execution across a 24-node GCP virtual-machine cluster.

2016–2022

Tomsk State University

Director of Data Science & HPC

Established a data science lab, managed a 12-engineer team, and mentored 30+ students across ML and software engineering.

2012–2016

Computational modeling research

Tomsk State University

Scientific simulation, predictive modeling, and parallel computing with C++, OpenMP, and MPI.

Modeling & decision science

Python · SQL · XGBoost · LightGBM · CatBoost · scikit-learn · calibration · SHAP · model validation & monitoring

Production engineering

FastAPI · Docker · Azure · GCP · CI/CD · Linux · typed APIs · regression validation · observability

Data & applied AI

Airflow · dbt · PostgreSQL · MS SQL · MySQL · Metabase · document AI · transformer embeddings · RAG / FAISS

Start a conversation

Building a team that takes ML
all the way to production?

I’m interested in senior data science and ML engineering roles with hands-on technical ownership. Based in Calgary, Canada.